How RAG Works, Step by Step
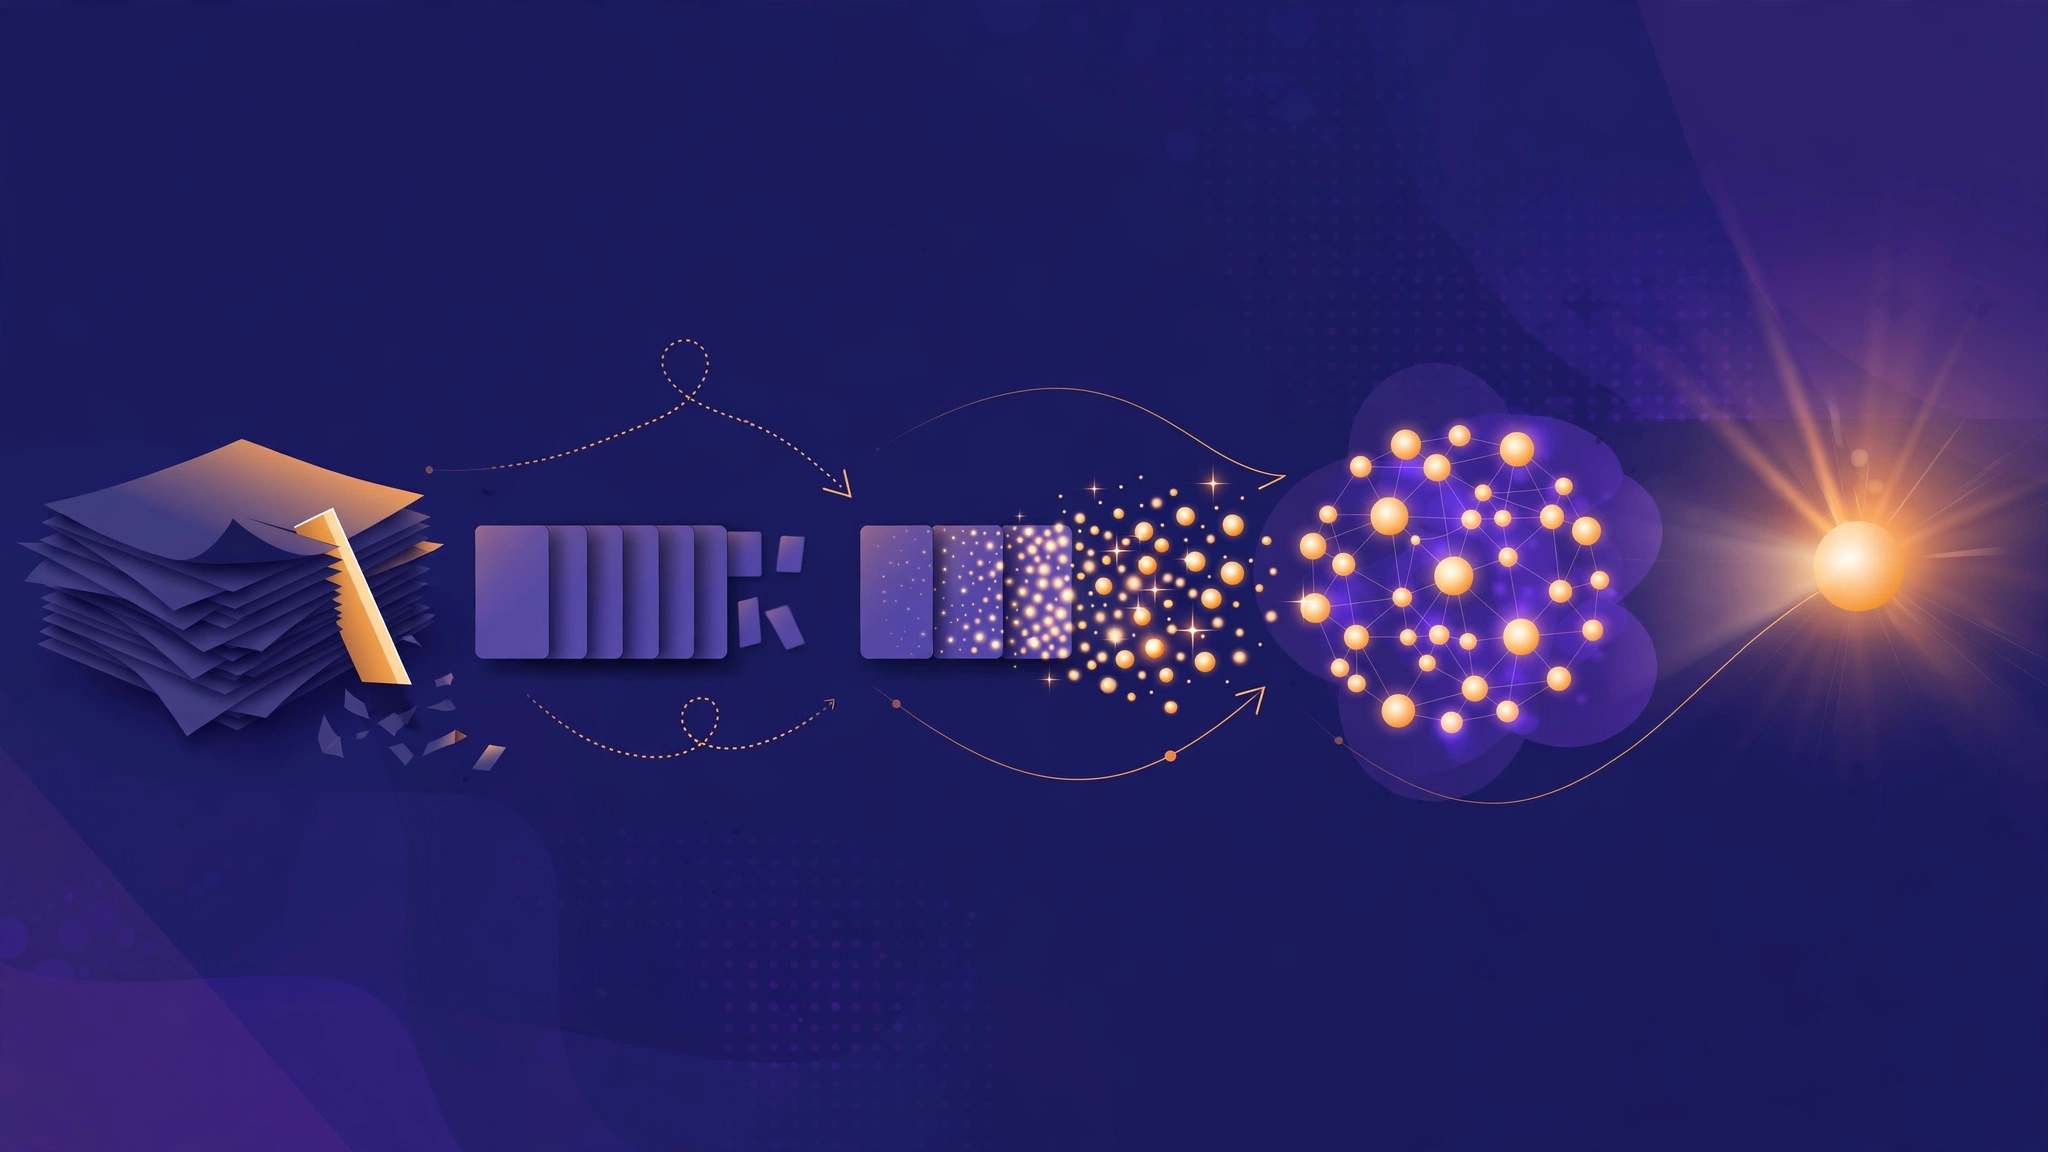
Part 2 of the RAG series. In Part 1 we said what RAG is. Here is how it actually works, one step at a time.
Nothing in this process is mysterious. It is a series of ordinary steps, done carefully, in the right order. If you understand the steps, you can judge any RAG system anybody tries to sell you, including ours.
Step 1: Collect the documents
It starts with the files themselves. Contracts, manuals, procedures, reports, whatever the system should be able to answer from. They are gathered into one place the system can read. This step is unglamorous and it decides more about the final quality than any other. A missing document is an answer the system can never give.
Step 2: Cut them into pieces
A 200 page manual is too big to hand to an AI for every question, and most of it is irrelevant to any single question anyway. So each document is split into small pieces, usually a few paragraphs each. This is called chunking.
Think of it as cutting books into index cards. Each card holds one idea, and the system will later pick out only the cards that match the question.
Step 3: Turn each piece into numbers
Here is the one part that sounds like science fiction. Each chunk is passed through a model that turns its meaning into a long list of numbers, called an embedding. Pieces that mean similar things get similar numbers, even if they use completely different words.
That is the quiet trick of the whole system. A question about “ending the agreement early” can find a clause that talks about “termination notice period”, because the numbers are close even though the words share almost nothing. Keyword search cannot do that. It only finds the words you already knew to type.
Step 4: Store the numbers
Those number lists, together with the text they came from, are kept in a special kind of database built for this job: a vector database. The next part of this series is entirely about that database, whether you need one, and how not to overpay for it.
Step 5: Ask a question, search first
You type a question. The question is turned into numbers the same way. The system compares those numbers against every chunk it stored and pulls out the handful of passages closest in meaning. This is the retrieval, the R in RAG. It takes a fraction of a second.
Step 6: Write the answer from the passages
Only now does the language model write. It receives your question and the passages that were found, and it is instructed to answer from those passages. The result is an answer in plain language, with the sources listed, so a human can open the exact page and confirm it.
Where quality is won or lost
Every step above can be done well or badly. Bad chunking cuts a sentence in half and loses its meaning. Outdated documents give outdated answers with complete confidence. A skipped source list makes the whole thing unverifiable.
The technology is not the hard part any more. The hard part is the same as in every system we have ever built for a client: clean input, a sensible process, and a way for a person to check the result. RAG is no different. It just makes the checking easy, if it is built honestly.
Ten questions about how work actually moves through your operation. No call, no slide deck.
If you want a second opinion on a specific decision, that conversation is free.
More from The Bridge
Don't Take My Word for It: Ask Your Own Documents
The series ends with a door, not a pitch: a working demo I built, with sample contracts, procurement and claims sets, so you can ask real questions and check the sources yourself.
Is RAG Safe for Company Documents?
Do your documents train the AI? Where do they live, and who inside your own company can find what? The safety questions worth asking any vendor, answered plainly.
When RAG Gets It Wrong
The honest part: bad documents, vague questions, clumsy chunking and a model that fills gaps. How RAG fails, and how a well built system earns trust anyway.